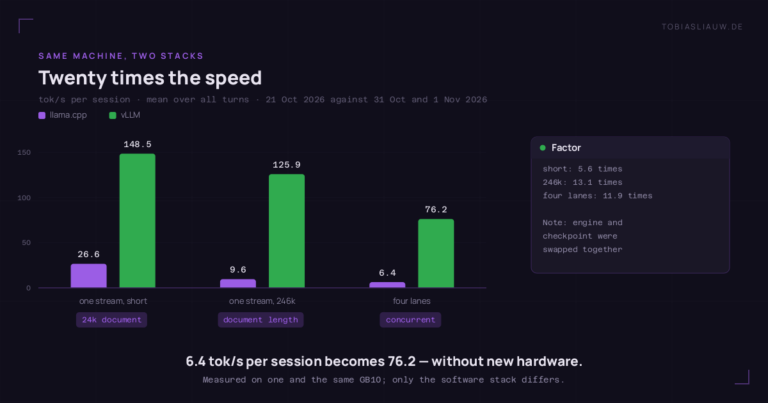
GB10: twenty times faster — partly because my first setup was wrong
On 21 October the model ran on the GB10 at 6.4 tok/s per session, on 31 October at 76.2 tok/s. The difference came from the stack underneath: vLLM instead of llama.cpp, FP4 weights, fp8 KV memory, three seats. Part of that factor is my first llama.cpp configuration, which I never checked. That measurement is still outstanding.